Your team has built a convincing demonstration. It reads an enquiry, looks up a product and drafts a reply. Then someone asks what happens when the buyer changes the quantity after approval, the inventory service is unavailable or the developer who built it goes on leave.
Those questions are not objections to AI. They define the product you actually need to buy or operate.
Build internally when the process is strategically distinctive and you can own its operation. Buy a specialist product when it already handles the process well. Consider managed delivery when the work crosses systems and needs ongoing exception resolution your team does not want to absorb. A hybrid can be the best choice: existing software for standard steps, with narrowly scoped integration and follow-through around it.
The comparison should use the same business result and service requirements for every option. Comparing a weekend prototype with a fully operated service is not a price comparison. It is a scope mismatch.
Define the result before the supplier
Take an inbound quotation process. “An AI that drafts emails” is too vague. A more useful scope is: turn eligible enquiries into a correct draft quote using the approved catalogue and price rules; hold ambiguous requests; get the required commercial approval; record what was sent; follow up under agreed rules; and reconcile an accepted quote to the order system.
Now list what remains outside scope. Perhaps engineering substitutions, new credit limits and price exceptions stay with named customer personnel. That is reasonable if the service obtains those decisions and resumes the work afterwards. It is less useful if every exception simply becomes another task in an unattended inbox.
Define acceptance at the level of an individual result. Which fields must be exact? Which sources must be referenced? Which decisions can be automated? What must be held? Which failure makes the result unacceptable regardless of the average accuracy?
This specification helps an internal team as much as a supplier. Without it, both can spend months improving a demo while disagreeing about what “finished” means.
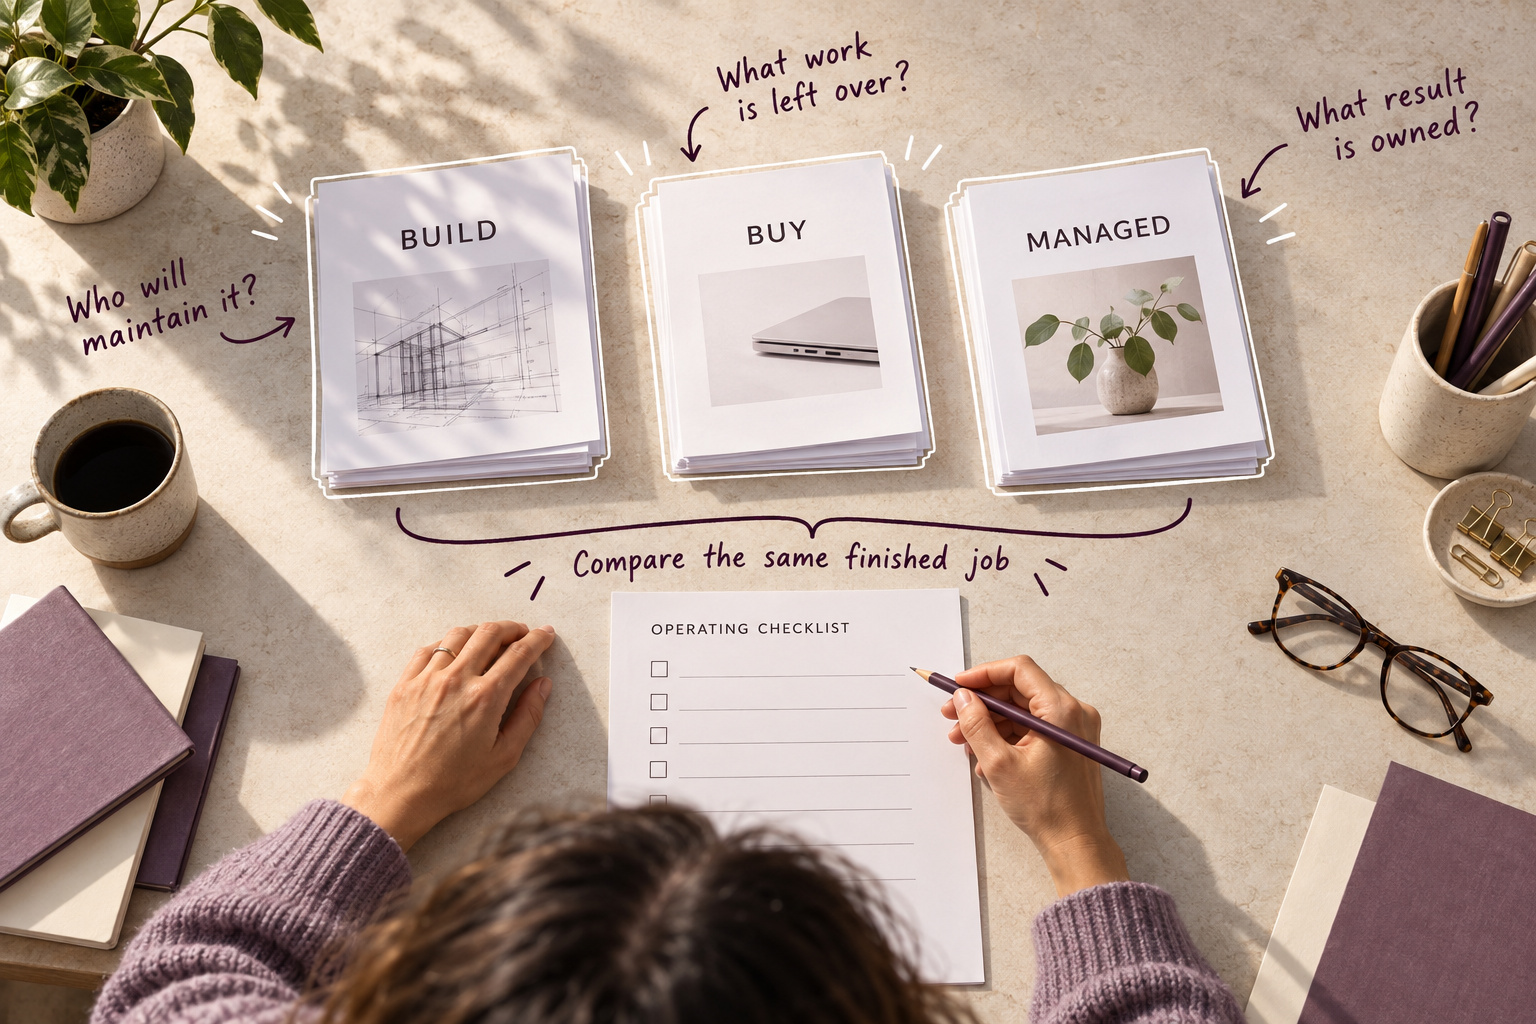
Read the visual explanation
Build when the process warrants it and your team can operate and maintain the system.
Buy when a product fits the job, accounting for configuration and work left outside it.
Define the managed result, customer decisions and responsibility for exceptions.
Compare the same finished job: who maintains an internal build, what remains outside a purchased tool, and what a delivery partner is responsible for completing. AI-generated illustrative scene; not a photograph of a Looqus client.
Ownership continues after launch
Configuration · integration · vendor dependency
Engineering · maintenance · on-call ownership
Service scope · exceptions · evidence of completion
Compare the whole operating responsibility, including what happens when the system fails.
The three options, without the sales caricature
| Option | Strong fit | Responsibility that remains |
|---|---|---|
| Build internally | Differentiating process, capable engineering team, sustained ownership | Operations, monitoring, evaluation, incidents, permissions and changes |
| Buy a specialist application | Standard process closely matches the product | Configuration, adoption, exceptions outside the product and vendor management |
| Managed delivery | Cross-system work needs ongoing execution and resolution | Customer policy decisions, access governance and agreed oversight |
| Hybrid | Existing tools cover most steps but handoffs fail | Clear division of responsibility between product, integration and people |
None is inherently more modern. A reliable existing order-management system may solve more of the problem than a custom agent. A custom build may be justified when the process is a genuine source of advantage. A managed service can be useful when the recurring coordination work is the part nobody currently owns.
The question is not whether a supplier uses AI. It is whether the resulting operating model is better than what you could reasonably assemble and maintain yourself.
Buying a platform still leaves decisions to make
A platform can provide substantial building blocks. LangGraph documents persistence, interruption and human review patterns, for example. Those capabilities can help a team build recoverable work, but they do not define your commercial rules or assign an owner to an ambiguous buyer request. LangGraph Functional API.
Licensing is also part of architecture. n8n’s guidance distinguishes internal client instances from other uses. Confirm the actual arrangement rather than assume any self-hosted software can be packaged into any commercial service. n8n licence-use guidance.
Microsoft’s Copilot Studio billing guidance shows why a familiar subscription label does not settle every cost question. Usage and licensing conditions need to be checked for the scenario and environment. Ask for an estimate based on the actual actions and expected traffic, not just the number of employees. Copilot Studio billing FAQ.
These examples are not a ranking of platforms. They illustrate separate obligations: execution behaviour, licensing and consumption. A buyer should expect the implementation partner or internal team to explain all three.
Compare costs on one sheet
Consider a fictional process handling 2,000 requests each month. The following numbers are planning assumptions, not market prices or a Looqus quotation. All options must satisfy the same acceptance and support requirements before this comparison is meaningful.
| Monthly equivalent | Internal build | Specialist product | Managed delivery |
|---|---|---|---|
| Setup amortized over 12 months | $2,000 | $500 | $1,000 |
| Software and infrastructure | $500 | $1,500 | Included in assumed service scope |
| Ongoing technical maintenance | $1,200 | $300 | Included in assumed service scope |
| Customer-side exception work | $1,800 | $1,200 | $400 |
| Assumed service payment | $0 | $0 | $3,000 |
| Illustrative total | $5,500 | $3,500 | $4,400 |
Under these assumptions, the specialist product is cheapest. That is a valid conclusion, not a problem to hide. If it actually completes the required process, the business should take it seriously.
Now suppose the product leaves an additional 40 hours of monthly cross-system work, valued at $40 an hour. Its total rises to $5,100. If the managed service already includes that same work, the comparison changes. But do not add the extra work to only one option unless evidence shows that difference. A fair comparison documents who performs each task.
Setup amortization is not cash flow. The internal build in this example implies a $24,000 setup outlay, even though the table spreads it across a year. A CFO may care about the initial cash commitment, implementation risk and time until benefit, not just the monthly equivalent.
If commercial terms include a performance component, model it explicitly. Define the outcome, baseline, attribution, exclusions, reporting period and dispute process. A fee tied to gross sales can behave very differently from one tied to contribution or accepted work. Avoid counting an assumed benefit as guaranteed income.
Count the work after a failure
A workflow can fail after it has already changed another system. For example, an order may be created while the acknowledgement is lost. A blind retry can create another order. Good recovery requires durable state, operation-specific duplicate controls and reconciliation.
Ask each option to demonstrate that case. Then change a quantity after approval. Does it invalidate the earlier approval? Ask what happens when a staff member loses access or a provider changes behaviour. These tests expose the difference between a functioning demonstration and an operable service.
The most revealing question is often, “Who will notice and who will close this?” Monitoring that produces an alert is only the first half. The second is authority and capacity to resolve the case, or obtain the decision from the person who has it.
Record ownership in plain language. The provider may diagnose the discrepancy, your commercial manager may authorize the exception, and the provider may resume and verify the action. Avoid a contract in which all three steps disappear behind “human in the loop.”
Risk management is a working practice
NIST’s AI Risk Management Framework is voluntary guidance for addressing trustworthiness through design, development, use and evaluation. It is not a certification that makes a deployment safe by reference. Its relevance here is the need to treat evaluation and management as continuing work. NIST AI RMF.
For a commercial workflow, translate that into concrete questions. Which data is needed? Which users can see it? What may the system send or change? How are mistakes corrected? What records are retained? What evidence will an operator see when approval is requested?
An answer such as “we use a leading model” does not address those questions. Neither does “it runs in your environment” if logs, integrations or support access cross other boundaries. Inspect the complete data path and the actual access controls for the proposed deployment.
Test before signing the full scope
Give every shortlisted option the same redacted cases and expected outcomes. Include ordinary work, missing information, changed documents and duplicate inputs. Specify which tasks must stop rather than guess. Keep a subset unseen until the final evaluation.
Evaluate the whole process. If the test stops at a draft, do not conclude that order completion is solved. If the pilot relies on a senior engineer manually repairing every exception, record that labour rather than hide it in the demonstration.
A sensible sequence is historical replay, shadow operation, reviewed live work and then carefully bounded automation. The duration depends on transaction frequency and risk; a calendar promise alone does not establish readiness. Each stage should have an exit condition and a rollback path.
The decision memo should include accepted-result rate, severe failures, correction hours, turnaround time, unresolved queue age and total cost. For sales impact, distinguish faster processing from incremental sales. The former may be demonstrated sooner; the latter needs a suitable comparison and time to mature.
Make the exit practical
Before buying, ask what you can export: business records, decision logs, configuration, prompts where applicable, test cases and integration documentation. Clarify software and model licence constraints. Make credential rotation and removal of provider access part of the exit process.
If you build internally, the equivalent question is whether another engineer can operate the system from the documentation. Dependence on one person is also a form of lock-in.
For a managed arrangement, define how open cases will be handed over. A folder of code is not enough if nobody can explain which customer commitments remain outstanding. The best handover preserves both the system and the state of the work.
When to speak with Looqus
Looqus is worth evaluating when the result spans several systems, the rules can be made explicit and someone needs to own the recurring follow-through. The conversation should establish what Looqus would operate, which customer decisions remain reserved, and how both sides will judge the result.
A specialist product may still be the better purchase. An internal team may already have the capacity. A useful assessment should make those alternatives clearer rather than pretend they do not exist.
Continue with the next decision
Use the AI ROI guide to develop the economic case and the enterprise deployment guide to examine the implementation responsibilities.
Sources
- LangChain documentation, LangGraph Functional API.
- n8n Help Center, Which licence do I need for my use case?.
- Microsoft Learn, Copilot Studio billing and licensing FAQ.
- NIST, AI Risk Management Framework.
Sources reviewed 14 September 2026. The cost scenario, evaluation design and purchasing recommendations are illustrative analysis, not a provider benchmark or guaranteed commercial outcome.
For listening or reading aloud
Read the spoken companion
Written companion transcript. Audio has not been recorded.
Should you build AI internally, buy software or pay someone to run the work? The answer starts with a less exciting question: what exactly needs to be finished?
If the requirement is simply to draft an email, many tools can help. If the requirement is to interpret an enquiry, check the catalogue, apply the right price, obtain approval, send the quote and follow it into an order, the scope is much larger.
A fair comparison gives every option that same scope. It is not fair to compare a weekend prototype with a fully operated service and conclude the service is expensive. It is equally unfair for a service provider to ignore a specialist application that already does the job well.
There are good reasons to build. The process may be distinctive, and your team may have the engineering and operating capacity. There are good reasons to buy. A mature product may solve a standard problem with less effort. Managed delivery becomes useful when the handoffs and unresolved cases are the part your team cannot absorb.
The cost table should reflect that. Include setup, software, infrastructure, maintenance and the human work that remains. Spread setup over a year if you want a monthly comparison, but show the initial cash outlay separately. Those are different views of the same investment.
Our fictional example deliberately makes the specialist product the cheapest option at first. Then we ask whether it leaves additional work outside the product. If it does, add that cost. If it does not, do not invent extra work to make another option look better.
The next test is failure. Suppose an order is created but the acknowledgement is lost. Does a retry create a duplicate? Suppose the quantity changes after approval. Does the system know the earlier approval is no longer sufficient? These are ordinary operating questions, not obscure technical tricks.
Ask who notices, who decides and who closes the case. An alert is useful, but it is not a resolution. A human approval step is useful, but only if the person sees the evidence and has the authority to make the decision.
Then test all options on the same examples, including the awkward ones. Measure correction time and severe errors as well as speed. Keep any manual repair work visible. A polished pilot can otherwise disguise an expensive operating model.
Finally, discuss the exit before the start. Can you export the records and understand the open cases? Can another engineer run the internal build? Can credentials be rotated and access removed? Independence is an operational capability, not just ownership of a code folder.
Looqus should be assessed against these same questions. If the work crosses systems and needs continuing follow-through, we can discuss a bounded scope. If a product or your internal team is the better answer, the comparison should show that. Describe a recurring task and where it gets stuck. No documents are needed for the first conversation. That gives us a more useful starting point than choosing an AI platform in the abstract.
AI does the work.We own the outcome.
Compare building, buying and managed delivery against the complete job, including the operating work and responsibilities your team would retain after launch.
- Agree the result
- Connect the work
- Own the follow-through